I used to think website visibility was mostly a Google problem. Get the page indexed, handle the SEO, build some links and move on.
That is not the whole picture anymore.
AI search has added another layer. A site can be public, load perfectly in a browser and even rank in Google while its robots.txt rules or technical setup make it harder for an AI search crawler to access the content.
That is why I built a free AI Readability Check on Marketur. I wanted a quick way to answer a simple question without digging through robots.txt files by hand: can AI systems actually access and understand this website?
ChatGPT search and AI training are not the same thing
This is the part that gets confusing.
OpenAI documents OAI-SearchBot as the crawler used for search discovery. OpenAI says sites that want content included in ChatGPT summaries and snippets should make sure OAI-SearchBot is not blocked. GPTBot is a separate crawler associated with potential model training use.
That means blocking every crawler with OpenAI in the name is not necessarily the same decision as saying you do not want your content used for training. You can make separate choices.
Start with robots.txt
Your robots.txt file is one of the first places to look. It can contain rules for specific crawlers or broad rules that apply to everyone.
The problem is that a robots.txt file can look simple and still behave differently than somebody expects. Specific user-agent groups and Allow and Disallow rules matter. I did not want the Marketur checker to just search the file for a crawler name and call it good. It parses the rules and reports what the configuration actually means for the crawlers it checks.
Google also documents the Robots Exclusion Protocol and how Allow and Disallow rules are interpreted. Google’s robots.txt documentation is worth reading if you want the technical details.
Google has separate AI controls too
Google-Extended is another reason not to lump every bot together. Google describes Google-Extended as a robots.txt control token related to the use of crawled content for Gemini training and grounding. Google also says it does not control whether a site appears in normal Google Search results.
So again, the question is not simply whether you “allow AI.” You need to know what a particular control actually controls.
Being crawlable is only half the job
Even when a crawler is allowed, I still want to know what it receives.
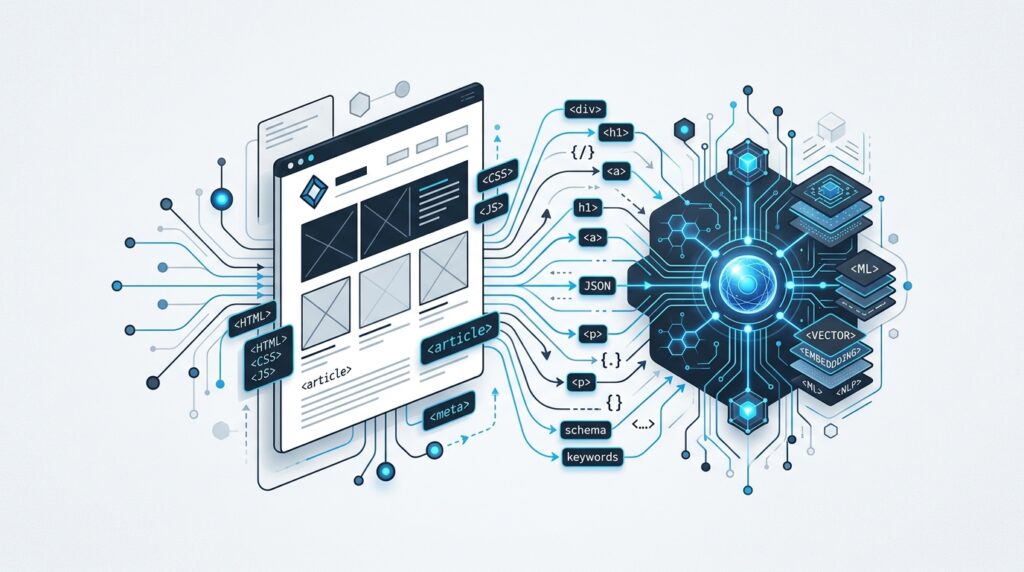
If the useful content only appears after a pile of JavaScript runs, or the page has weak titles, no useful heading structure, missing canonical information or no clear business identity, allowing the crawler does not magically make the page easy to understand.
That is why the Marketur tool also checks the page itself. I want to know whether the important content is present in the HTML, whether basic metadata exists, whether structured data identifies the business and whether the page gives a machine something useful to work with.
Check your site instead of guessing
I expect this whole area to keep changing. Crawlers will change, AI products will change and the controls site owners get will change with them.
What I do not want to do is blindly copy a robots.txt block from a post written two years ago and assume it still represents what I want.
Run your website through the free Marketur AI Readability Check. It will show you what it finds and help separate AI search access from training access so you can make the choice yourself.